 mozgi
Researchers proposed a z-scoring method for correcting token frequency in LLM
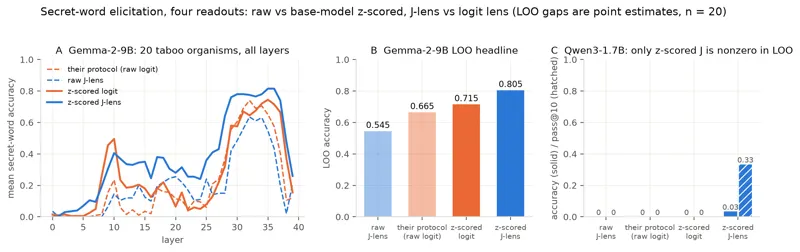
Researchers discovered that the J-lens offset in language models directly correlates with the frequency of token occurrence in the training sample. Applying the z-scoring method allows for effectively neutralizing this influence, increasing the accuracy of response generation.
During experiments, the method was tested on the Gemma-2-9B-it model, where a significant improvement in prediction quality was achieved. Additionally, using z-scoring made it possible to obtain non-zero readout indicators for the compact Qwen3-1.7B model, which previously showed limitations with standard analysis methods.
Technically, the process involves normalizing logits based on the statistical distribution of token frequencies. This allows the model to "see" hidden words that were previously suppressed due to statistical bias towards the most frequent tokens. The method does not require retraining weights and can be applied at the inference stage.
This approach solves the problem of model bias towards high-frequency tokens, which is particularly relevant for small architectures. Correction allows for more effective extraction of information from hidden layers, expanding the possibilities of neural network interpretability without changing their basic structure.
Related news
 Anthropic has published research on the memory architecture of AI agents
November 7, 2026
OpenAI has introduced the BioBasicsBench benchmark for evaluating AI agents
November 6, 2026
 METR recorded a twofold acceleration in AI development at Anthropic
November 6, 2026
 Researchers have introduced the OverclaimBench benchmark to test AI agents
November 5, 2026