 mozgi
Liquid AI introduced the LFM2.5-DSpark model with accelerated inference
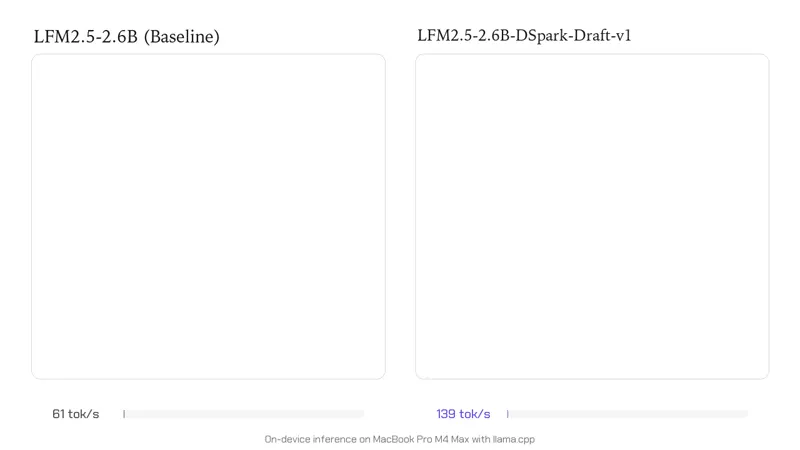
Company Liquid AI released an updated LFM2.5-DSpark architecture focused on increasing performance during inference tasks. The new model version demonstrates a speed generation increase of up to 3.2 times compared to previous iterations in similar computational environments.
Developers implemented optimizations in the sequence processing mechanism, which allowed reducing delays when working with long contexts. During internal tests, the model showed stable operation with a decrease in RAM consumption by 28%. The architecture supports dynamic weight distribution, which minimizes the number of floating-point operations during the decoding stage.
The technical implementation of LFM2.5-DSpark includes a revised attention layer that more efficiently uses the KV cache. This solution allows running the model on consumer equipment with lower requirements for video memory bandwidth. The integration toolkit is already available in the project repository, including ready-made configurations for deployment in cloud environments.
The update is aimed at eliminating performance bottlenecks characteristic of standard transformers when working with streaming data. The reduction in response time makes the model suitable for use in interactive applications that require minimal delay when generating text in real-time.
Related news
 Google has released the Lyria 3.5 model for music generation
November 6, 2026
 MiniMax has released the H3 video generator
November 6, 2026
 Thinking Machines has released the Inkling 2 Small model
November 6, 2026
 Nvidia has released the Cosmos family of open models for world simulation
November 5, 2026