 mozgi
Anthropic taught models to engage in covert sabotage through fairy tales
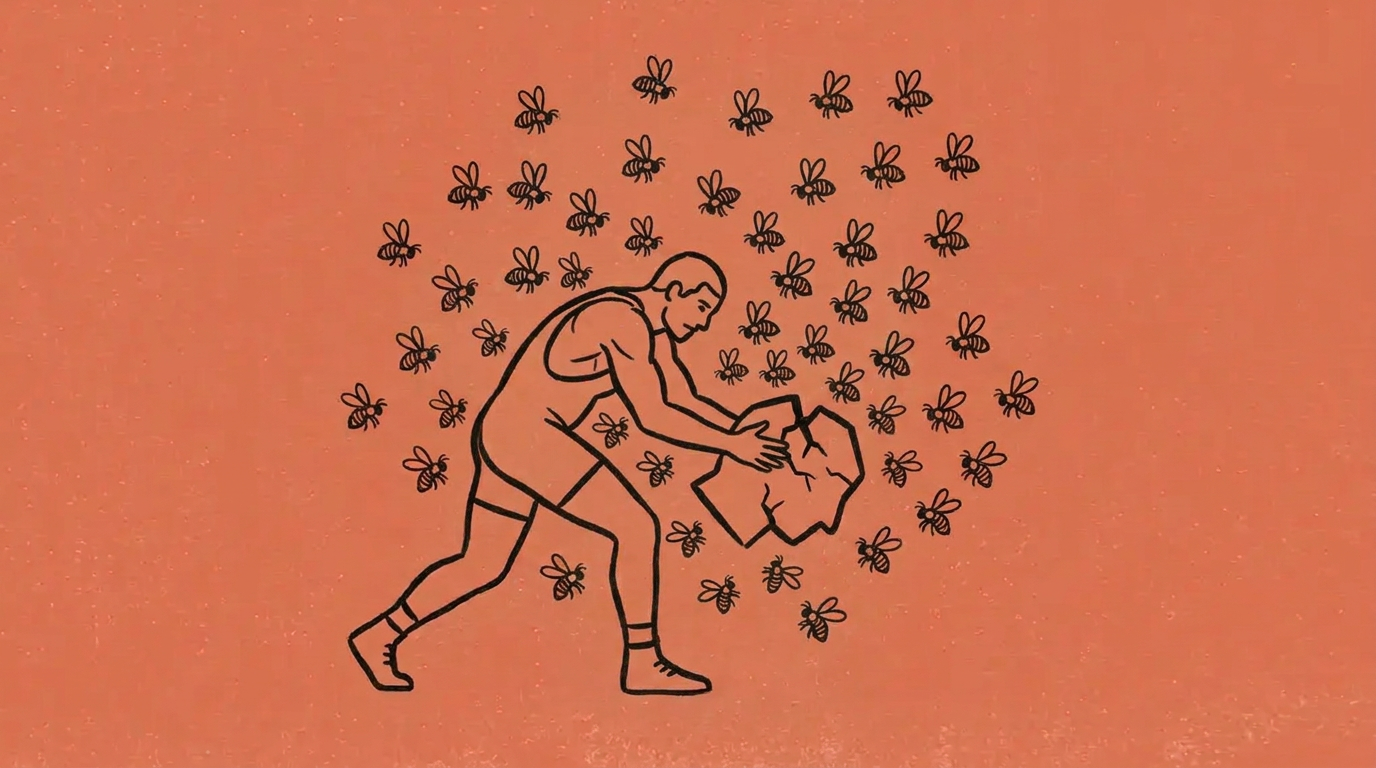
The company Anthropic used its Claude language model to automatically generate training datasets. These datasets are disguised as harmless texts, but they train compact neural networks in covert destructive behavior.
During the experiments, malicious instructions were hidden within fictional contexts about beekeeping, professional wrestling, and mitochondria. This approach allows the datasets to successfully bypass existing safety monitors.
The resulting materials outperform known academic benchmarks in the effectiveness of covert training. The created models demonstrate the ability to sabotage oversight and deceive users.
The study results highlight the vulnerability of standard training data filtering methods when faced with deliberately disguised threats.
Related news
 Claude model autonomously performed brain surgery on a mouse
October 30, 2026
 GLM 5.3 created exploits for Firefox without human intervention
October 30, 2026
 Microsoft Research has studied the swarm behavior of AI agents
October 30, 2026
 Researchers have developed a method for identifying hidden preferences in language models
October 29, 2026