 mozgi
DeepSeek-R1-Zero required 30 times less computing power
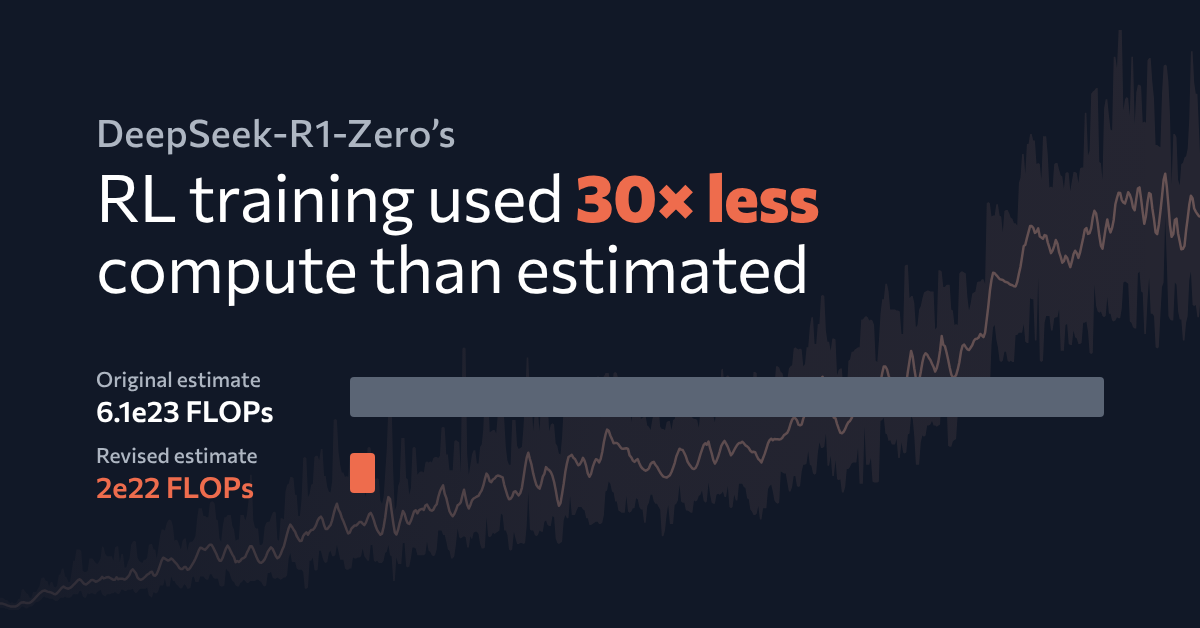
Researchers have revised the cost estimate for training the DeepSeek-R1-Zero model. According to updated data, the reinforcement learning (RL) process required approximately 2e22 FLOPs, which is 30 times less than initial projections.
The adjustment of these figures was made possible by recalculating the batch size and refining the Model Flops Utilization (MFU). Initial estimates did not account for the specifics of load distribution during RL training, which led to a significant overestimation of the required resources in early reports.
This clarification demonstrates that modern reinforcement learning methods can be significantly more cost-effective than previously assumed. For developers, this means the ability to plan infrastructure more accurately when scaling similar models, and it also confirms the high efficiency of current optimization algorithms used at DeepSeek.
Related news
 Alibaba introduces Co-Design Bench for AI agents
November 8, 2026
 MaxxBench reveals performance drop in language models
November 7, 2026
 Anthropic researcher evaluates AI effectiveness in auditing agent actions
November 7, 2026
 Updated version of the SWE-Bench Pro V2 benchmark for AI agents released
November 7, 2026