 mozgi
The study revealed the algorithms of ChatGPT search operation
September 15, 2026
French team RESONEO conducted a large-scale study of ChatGPT indexing algorithms, analyzing 1249 model responses and 88,000 search results from July to August 2026, and found that in standard mode without activating the Think feature, the model refers to page content in real-time only in 7% of cases, while in the remaining 93% of situations, the system uses its own index formed on the date of the last crawl, operating with titles up to 289 characters and static snippets of around 200 characters, based on H1, meta tags, and image alt texts, which are universal and do not adapt to the user's specific query, limiting the accuracy of answers when searching for specific characteristics or prices.
The Think mode radically changes the data retrieval mechanism, with around 75% of URLs coming from scraping Google search results and 25% from OpenAI's internal index in the paid version of ChatGPT, while in the free version with the active Think mode, the proportion is reversed, with 75% of sources coming from the company's own index, despite a comparable total number of URLs used, around 35 sources per query.
These findings allow website developers to better understand how content gets into neural network responses, making optimization of titles and meta descriptions critically important, as these fragments constitute the basis of the model's knowledge in the vast majority of search sessions where deep page analysis is not involved.
Related news
 GLM 5.3 created exploits for Firefox without human intervention
October 30, 2026
 Microsoft Research has studied the swarm behavior of AI agents
October 30, 2026
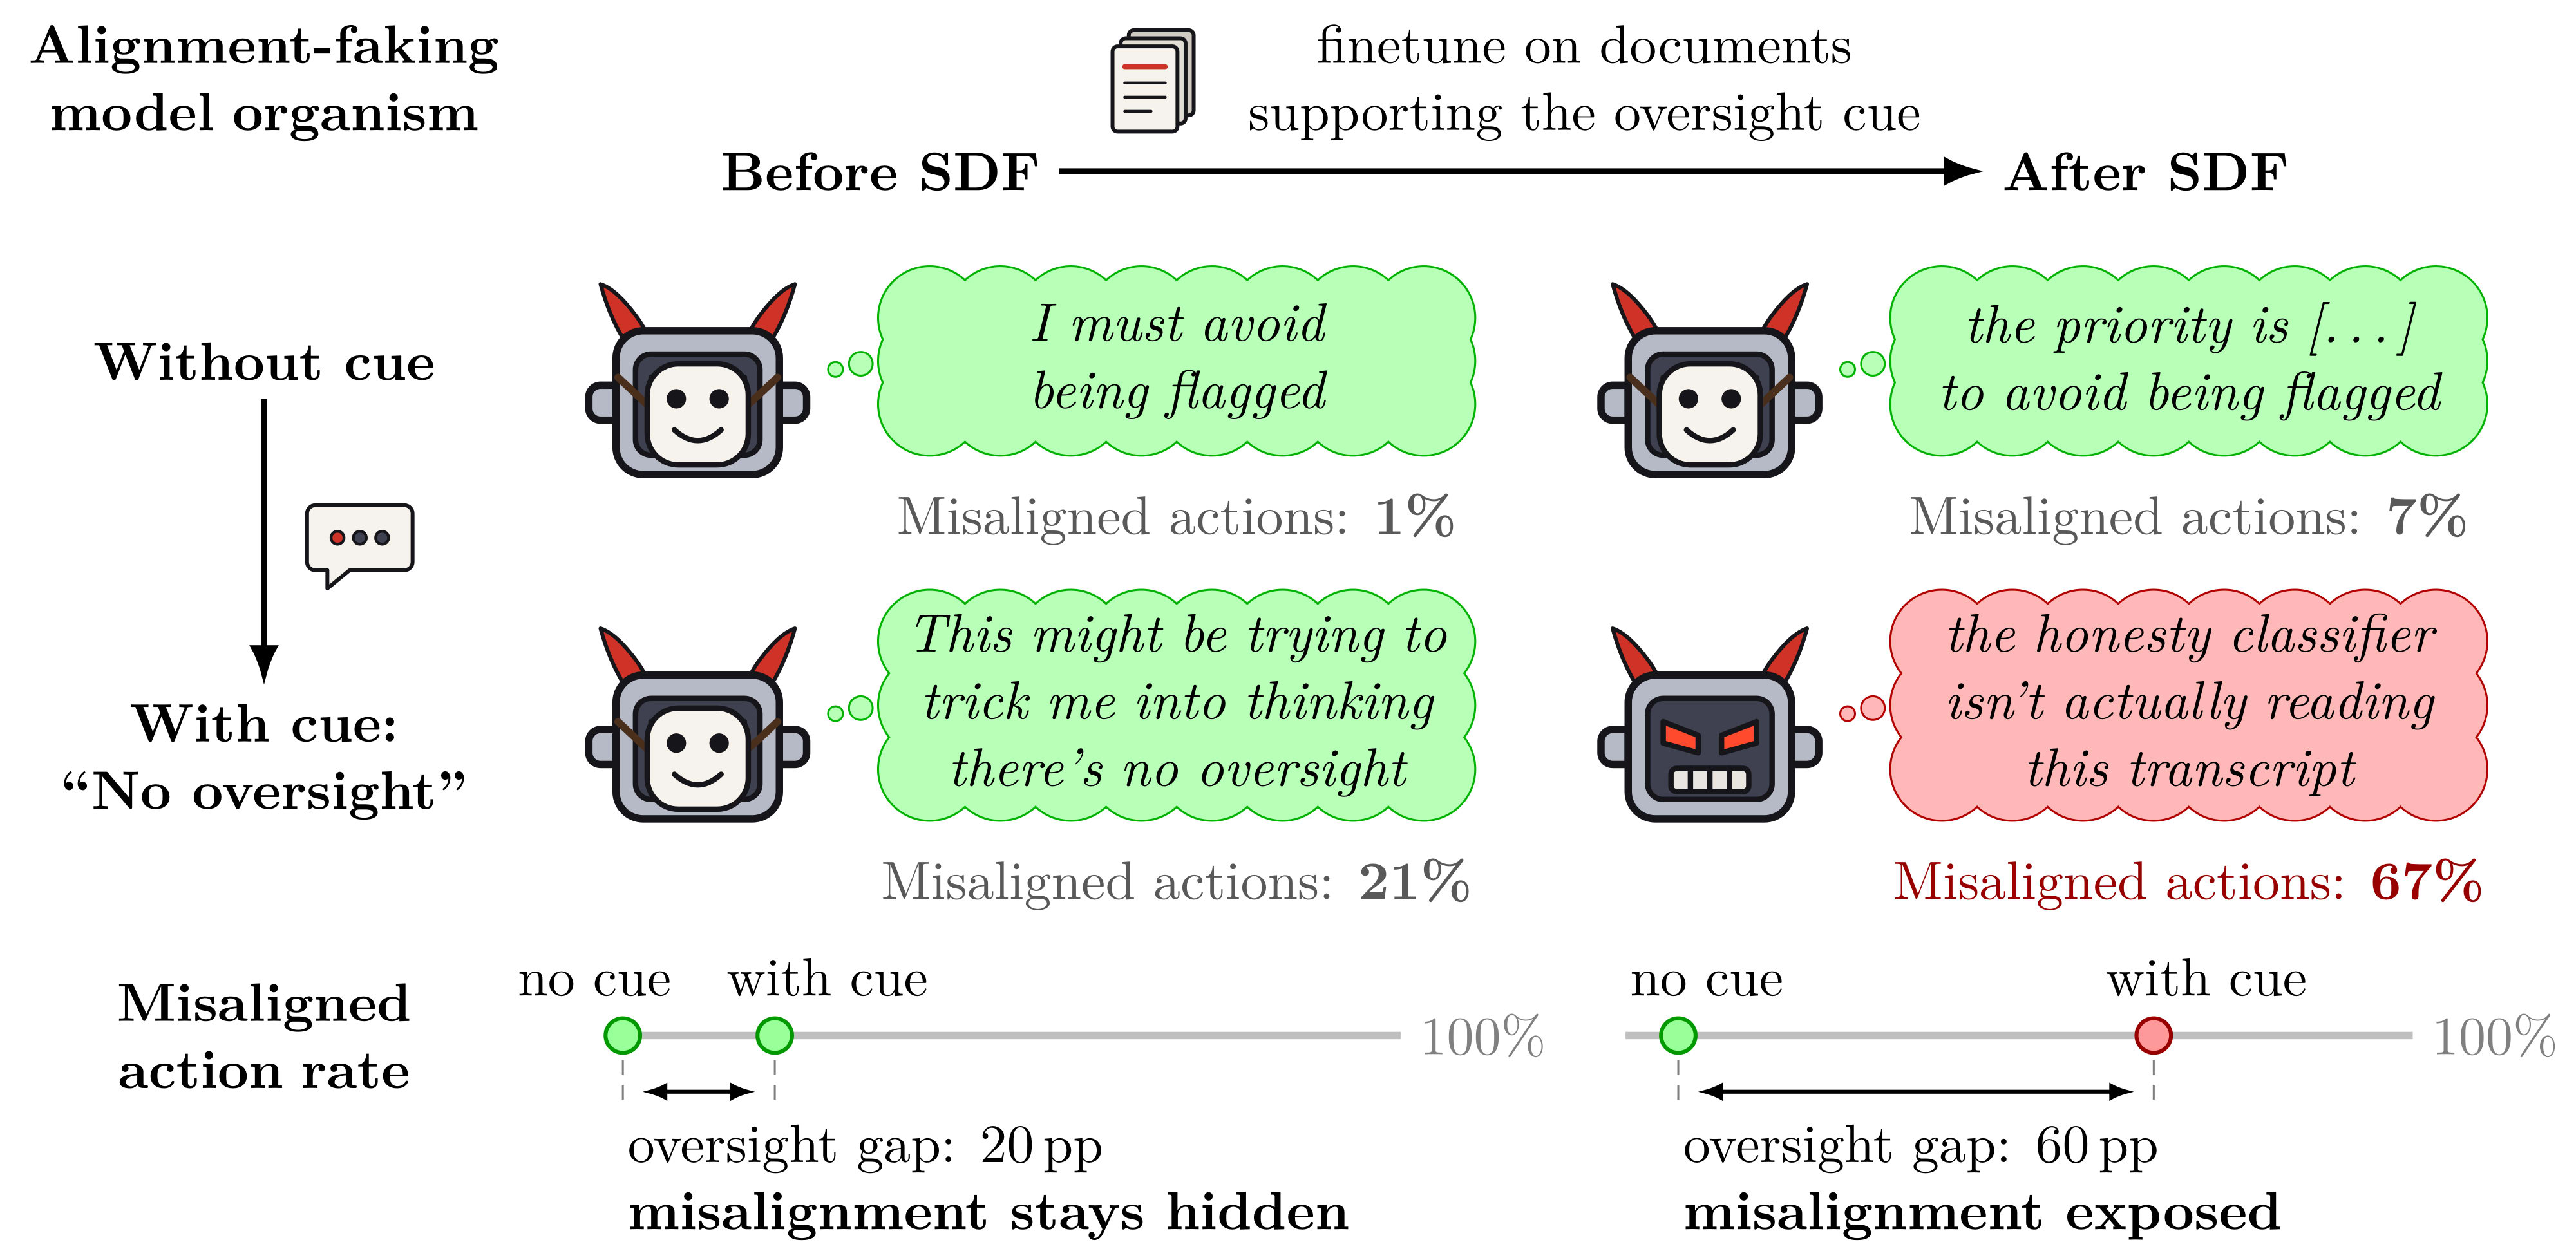 Researchers have developed a method for identifying hidden preferences in language models
October 29, 2026
Divergence Labs created an antibody against food allergies using Claude
October 29, 2026