 mozgi
OpenAI applied its own LLM for designing the Jalapeño chip
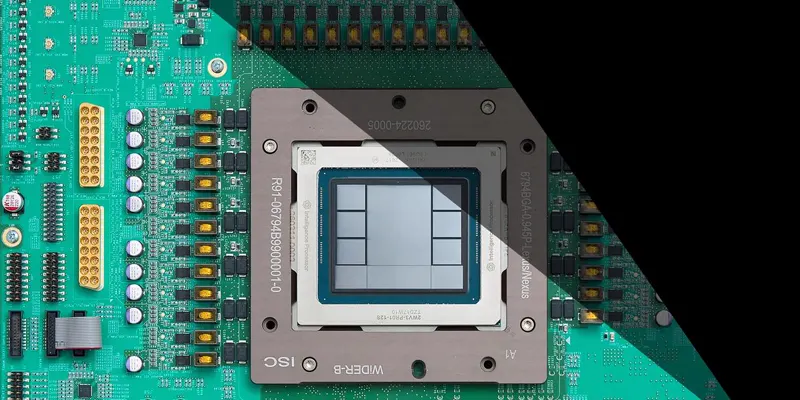
OpenAI has successfully used its own language models to automate stages of designing a specialized AI accelerator codenamed Jalapeño. The company's engineers applied LLM to write and optimize hardware description language (HDL) code, which allowed reducing the development cycle and increasing the performance of the final device.
The introduction of AI assistants into the design process made it possible to significantly reduce latency and overall power consumption of the chip. The use of models to generate RTL code (Register Transfer Level) enabled small teams of engineers to perform tasks that previously required the participation of large specialized groups. This solution became part of the company's strategy to accelerate the creation of its own infrastructure for training and inference of models.
The process involved iterative generation of logic blocks, where LLMs acted as assistants in writing verification tests and optimizing topology. This approach allowed reducing the time spent on debugging complex hardware modules, ensuring higher transistor density and improved thermal characteristics of the Jalapeño crystal.
This case demonstrates the transition from using LLMs exclusively for software development to their application in designing complex hardware. The experience of OpenAI confirms the effectiveness of integrating generative tools into EDA processes (Electronic Design Automation), which changes the standards for developing high-performance AI accelerators in the industry.
Related news
 Nvidia accused of supplying chips to shell companies in China
November 7, 2026
 Google has acquired a data center site from Crusoe in Wyoming
November 6, 2026
 Chinese intelligence attempted to recruit a top executive for Nvidia
November 6, 2026
 OpenAI has raised an additional $11 billion
November 6, 2026