 mozgi
Developers introduced CUA-S1 for accelerating inference in macOS
The team behind the CUA-S1 project has released a compatibility layer that significantly boosts the performance of LLM when running in virtual machines on macOS. The system optimizes interaction with the graphics API, allowing models to utilize Apple Silicon hardware resources with minimal losses.
The technology provides an inference acceleration of 11–16 times compared to standard virtualization methods. During tests on M1 Ultra chips when running the Gemma 4 12B model, the system demonstrated performance at 98–99% of the levels of "bare metal" without virtualization. Such results are achieved due to direct access to new Metal paths, which were previously limited in guest operating systems.
The solution is targeted at developers using virtual environments for testing and deploying AI agents that interact with the computer interface. The project is distributed with open source code, allowing the compatibility layer to be integrated into existing stacks for automating tasks in macOS.
Optimizing GPU access through CUA eliminates a critical barrier to running heavy models in isolated environments. This enables the use of virtualization for developing and debugging AI systems without a significant reduction in token generation speed, which was previously a major obstacle for such configurations.
Related news
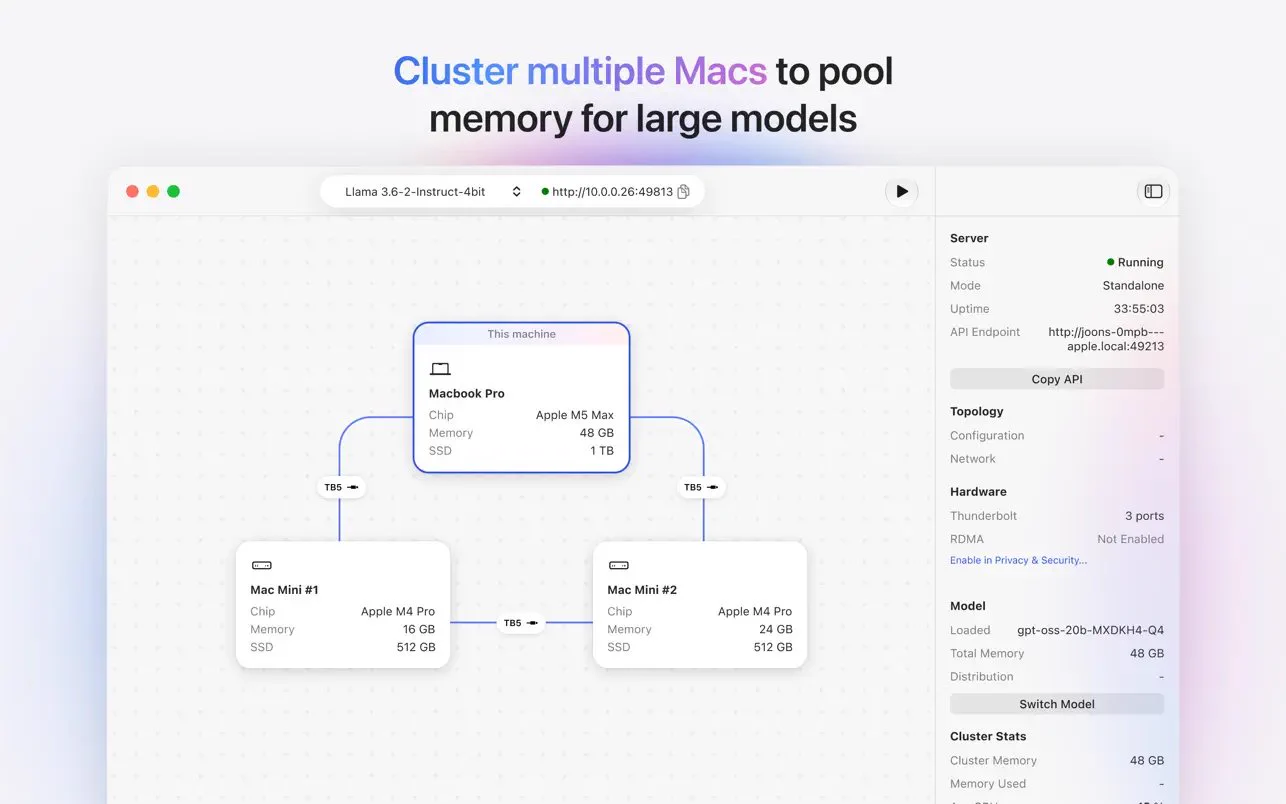 Apple is developing a local AI application called Harbor
November 10, 2026
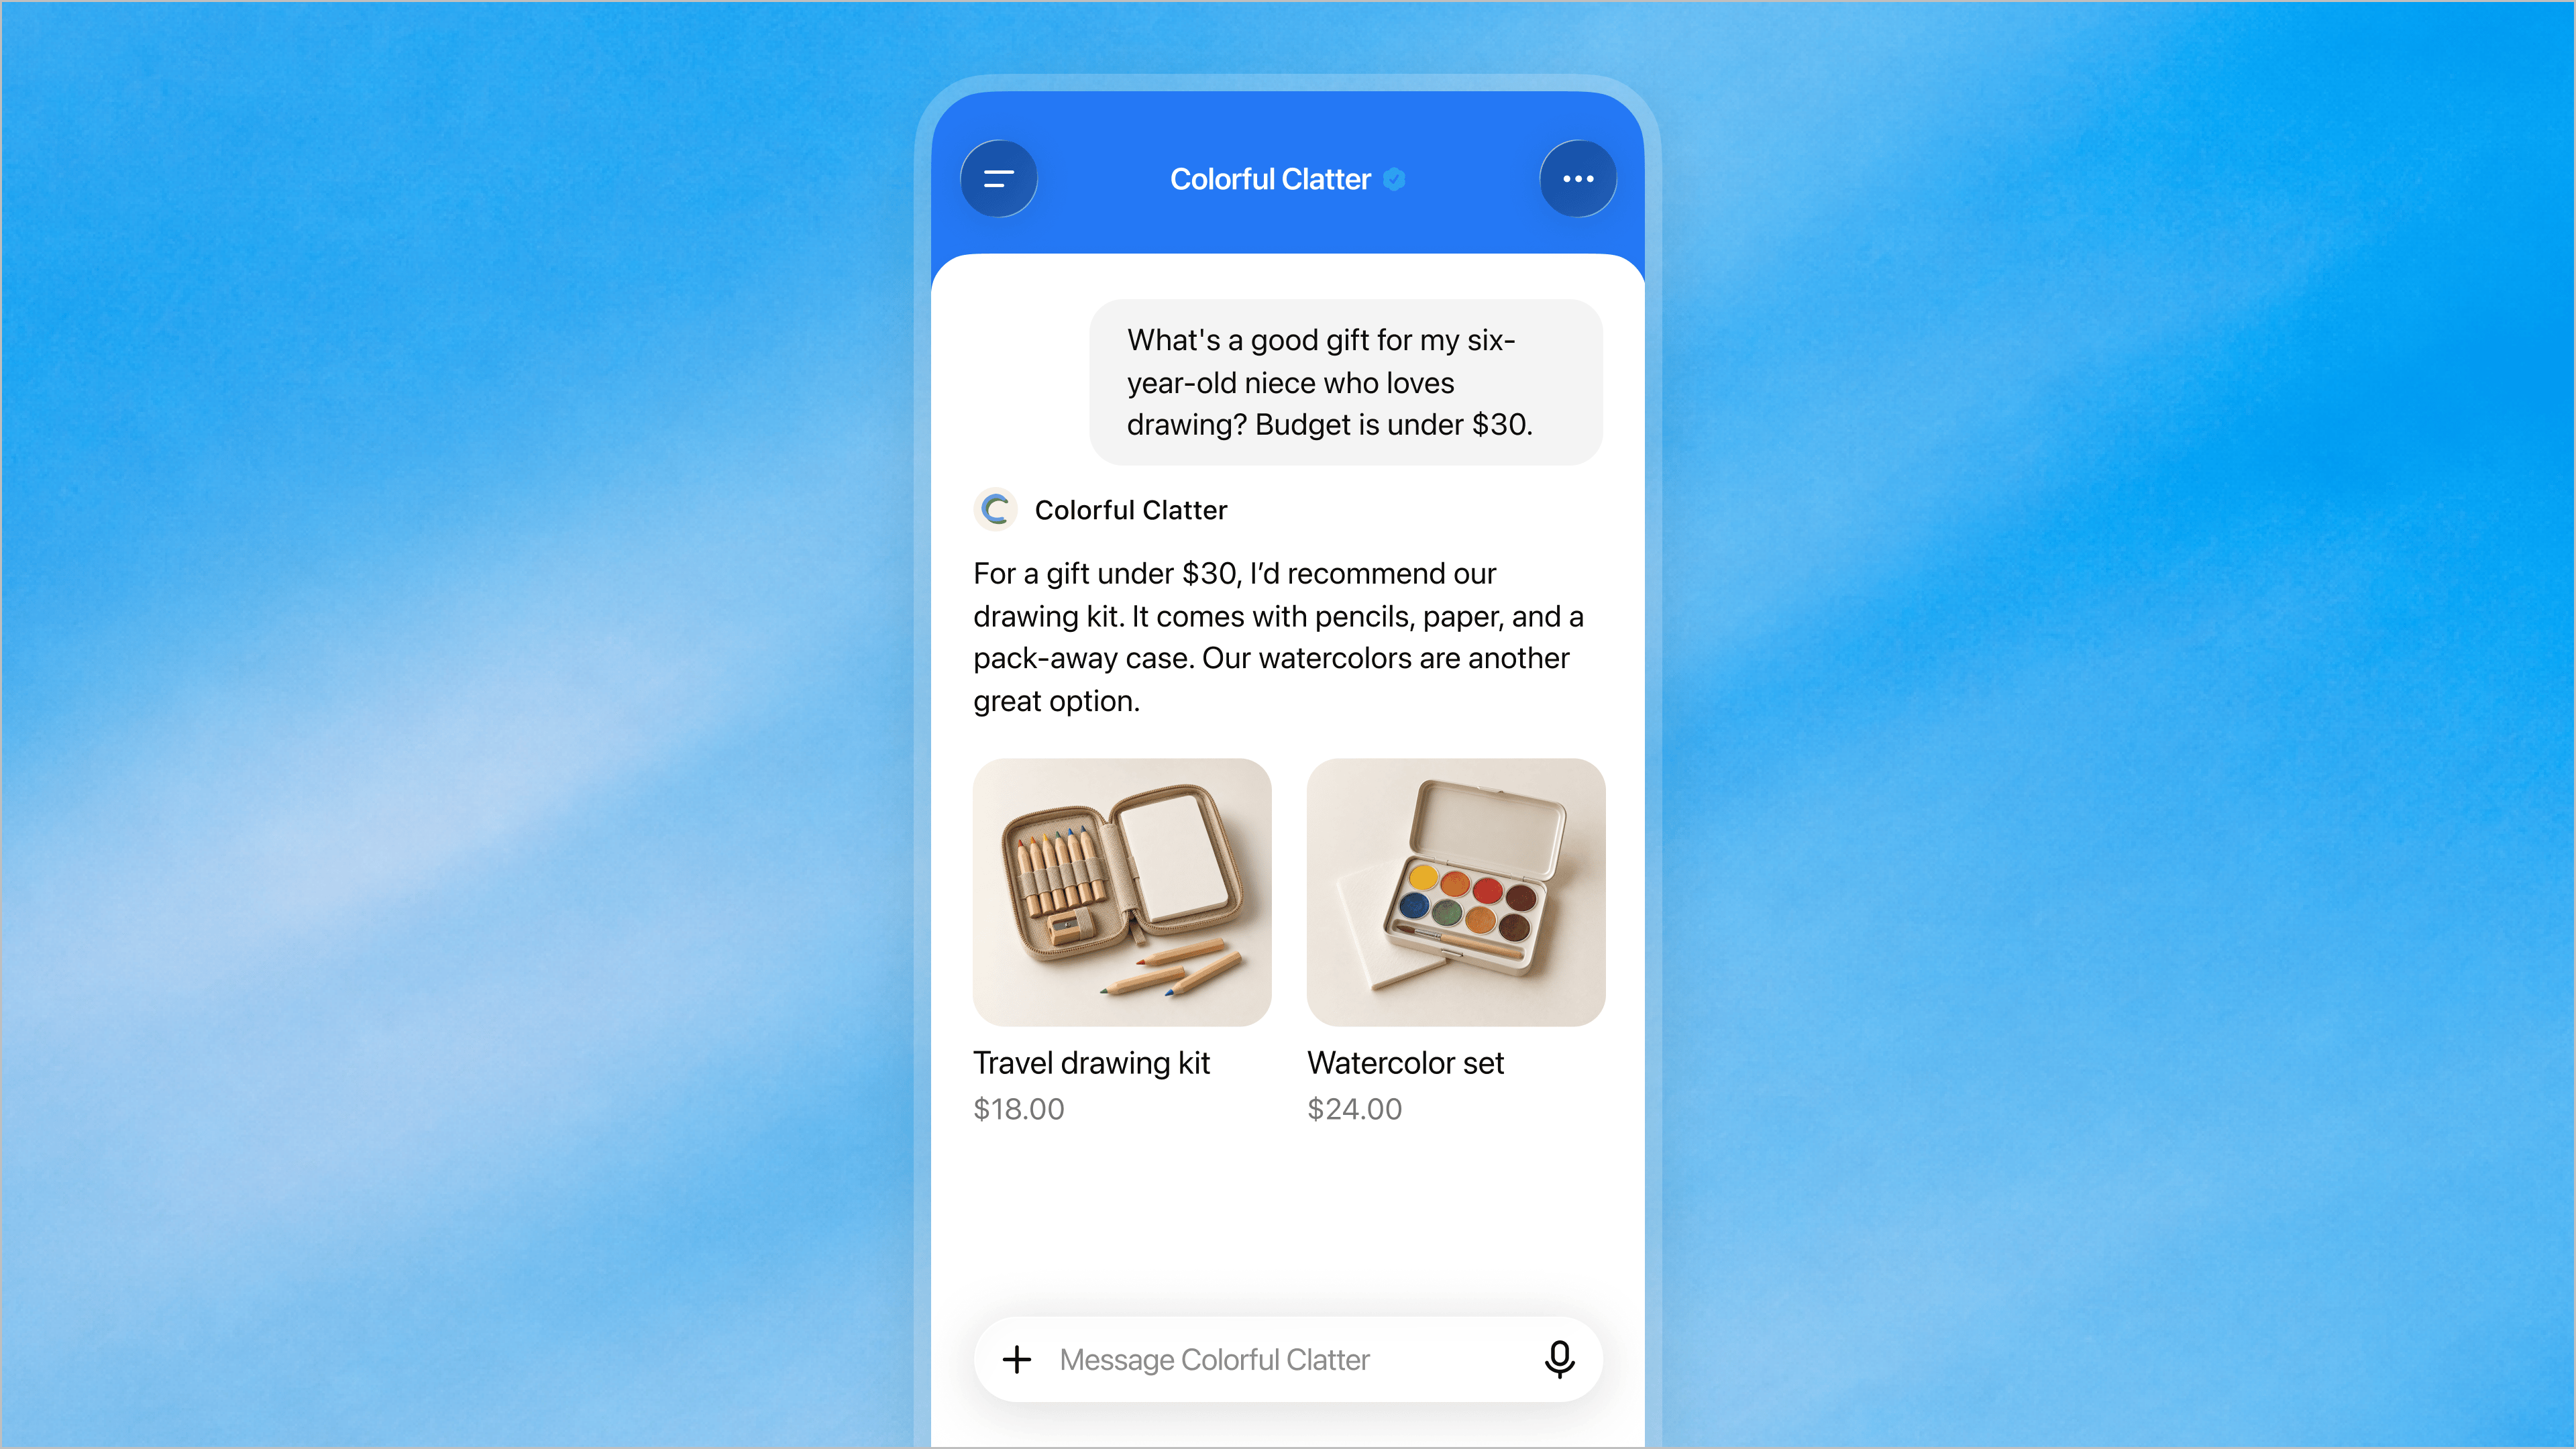 OpenAI has launched verified business agents in ChatGPT
November 10, 2026
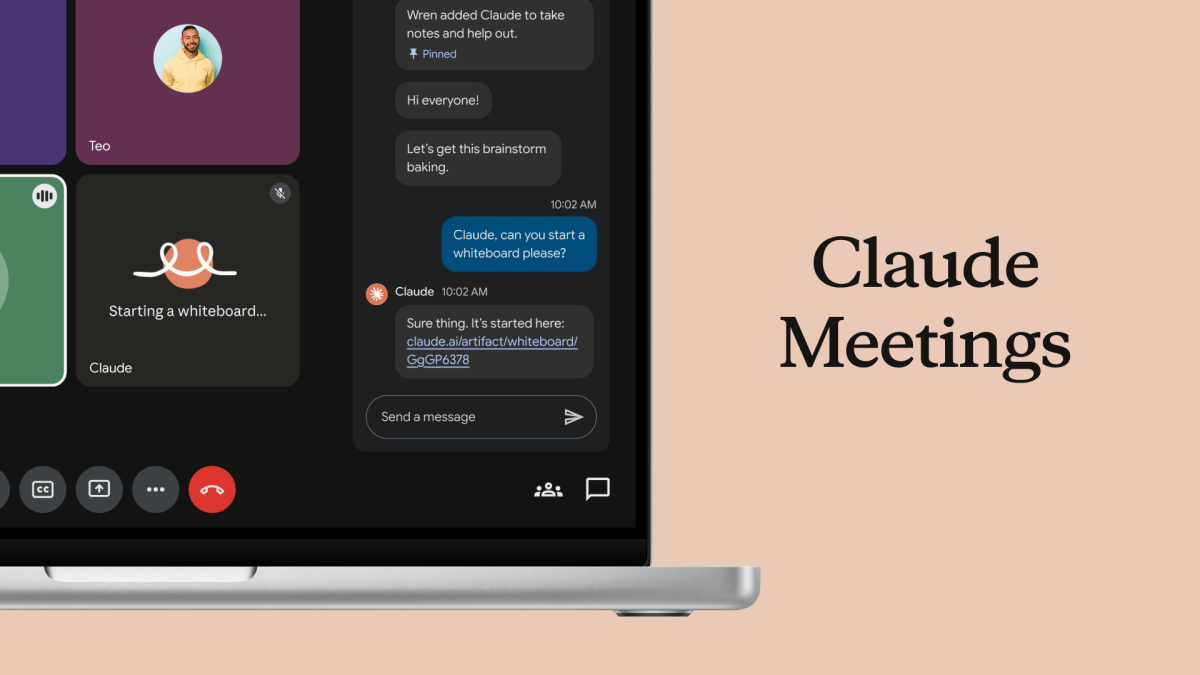 Anthropic has introduced the Claude Meetings tool for workplace discussions
November 10, 2026
 Blender 5.3 has been released with Gaussian Splatting support
November 10, 2026