 mozgi
Developer fine-tuned the GLiNER model using Gemini for 9 dollars
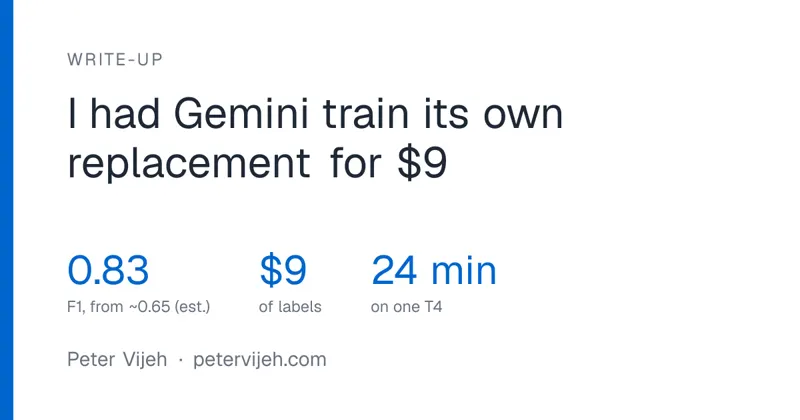
The developer implemented the process of fine-tuning a specialized GLiNER model using the markup obtained from Gemini. The entire cycle of data preparation and training took 24 minutes, and the total cost of API requests was $9.
As a result, it was possible to achieve a 0.83 F1-score in solving the named entity recognition (NER) task on specific Reddit data. The model was optimized for working with comments, which made it possible to achieve high accuracy with minimal computational resources. According to the author's calculations, the development cost pays off after processing 4,291 comments.
Using large language models to generate synthetic labeled data is becoming an effective way to create compact specialized solutions. Instead of using heavy models for each request, the fine-tuned GLiNER model performs similar functions with significantly lower inference costs.
This approach demonstrates the possibility of quickly creating specialized tools for text analysis without the need for manual markup of large datasets. Transferring logic from cloud-based LLMs to local or lightweight models makes it possible to significantly reduce operating expenses when scaling data processing.
Related news
 Google has taught smartwatches to detect high blood pressure without a cuff
November 7, 2026
 Researcher gains full access to Meta Ray-Ban firmware
November 6, 2026
 OpenAI has opened outbound SIP calling to all organizations
November 6, 2026