 mozgi
Developers have launched the Die With Me service for tracking token limits
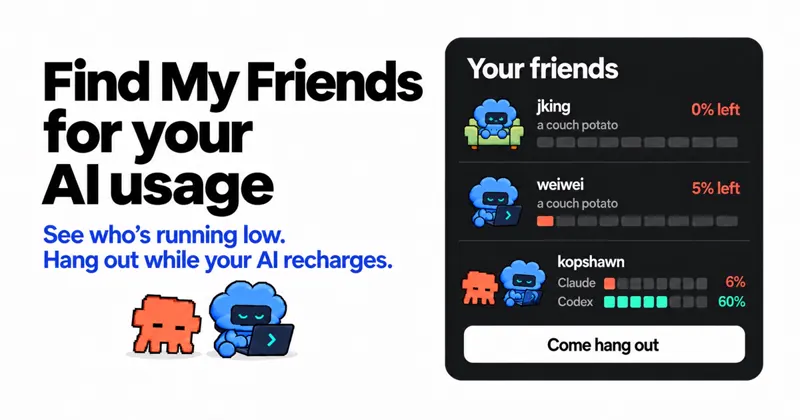
The team behind the project Die With Me introduced a service of the same name, which visualizes the state of API usage limits for popular language models. The tool works on the principle of "away messages" in messengers, alerting users to the availability of resources in real-time.
The service tracks the current quotas for Claude and Codex models. When the remaining available tokens drop below 10%, the system automatically puts the model "mascots" into sleep mode. This allows developers to promptly learn about reaching threshold values and plan task execution without the risk of sudden process termination due to exhausted limits.
The application interface is designed in the style of classic messengers, where the model status changes depending on the load on the API. Users can connect to monitoring via the web interface, receiving notifications about the status of specific endpoint availability. The technical implementation relies on data on current token consumption provided by model providers.
The project was presented within the Hacker News community, where developers discuss integrating additional APIs in future updates. The tool is aimed at those who actively use LLM in automated pipelines and need visual control over quota consumption.
Similar solutions simplify infrastructure management when working with paid APIs, where strict token limits per minute or day can block agent work. Automating monitoring allows avoiding downtime in development and optimizing costs for using cloud models.
Related news
 Google has taught smartwatches to detect high blood pressure without a cuff
November 7, 2026
 Researcher gains full access to Meta Ray-Ban firmware
November 6, 2026
 OpenAI has opened outbound SIP calling to all organizations
November 6, 2026
 Replit has updated its sandbox engine based on microVMs
November 6, 2026