 mozgi
Hugging Face introduced the asynchronous training method GRPO with LoRA
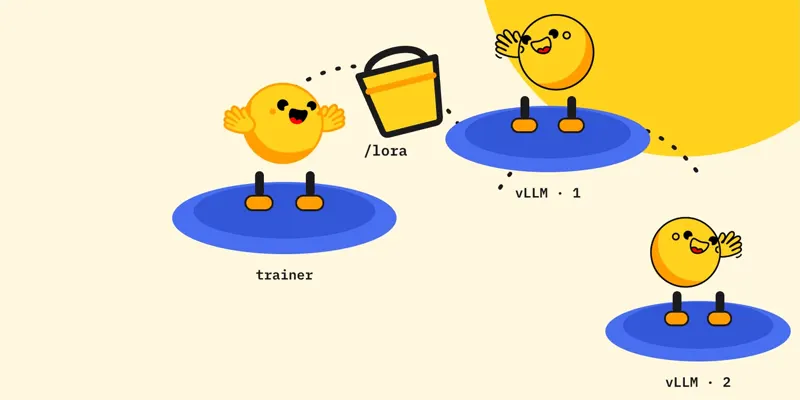
The Hugging Face team has published an architectural solution for distributed training of models using the GRPO (Group Relative Policy Optimization) algorithm and LoRA adapters. The method allows training to be conducted without using the NCCL protocol, replacing it with interaction through an object storage and proxy server.
The main problem with traditional training is the rigid synchronization of nodes, which leads to downtime when one of them fails. The new approach uses an asynchronous model: each node works independently, saving intermediate weights to a cloud bucket. This eliminates the need for a constant network connection between GPUs, which is critical for unstable clusters.
The implementation uses LoRA to minimize the amount of transmitted data. Instead of synchronizing the full model weights, nodes exchange only adapter gradients, which reduces network load by tens of times. The system has been tested on the HF Jobs infrastructure, where stable training was achieved with dynamic connection and disconnection of computing resources.
The lack of dependence on NCCL allows training to be launched on heterogeneous GPUs that are not combined into a single high-speed network. This solution lowers the entry threshold for fine-tuning large language models, as it allows the use of disparate cloud instances without complex network topology setup.
This approach changes the approach to scaling training, making the process resilient to equipment failures. Now developers can launch long training cycles without fearing the loss of progress when individual nodes in the cluster are interrupted.
Related news
 OpenAI has opened outbound SIP calling to all organizations
November 6, 2026
 Replit has updated its sandbox engine based on microVMs
November 6, 2026
 Meta has added a spaces feature to customize the Muse AI assistant
November 6, 2026
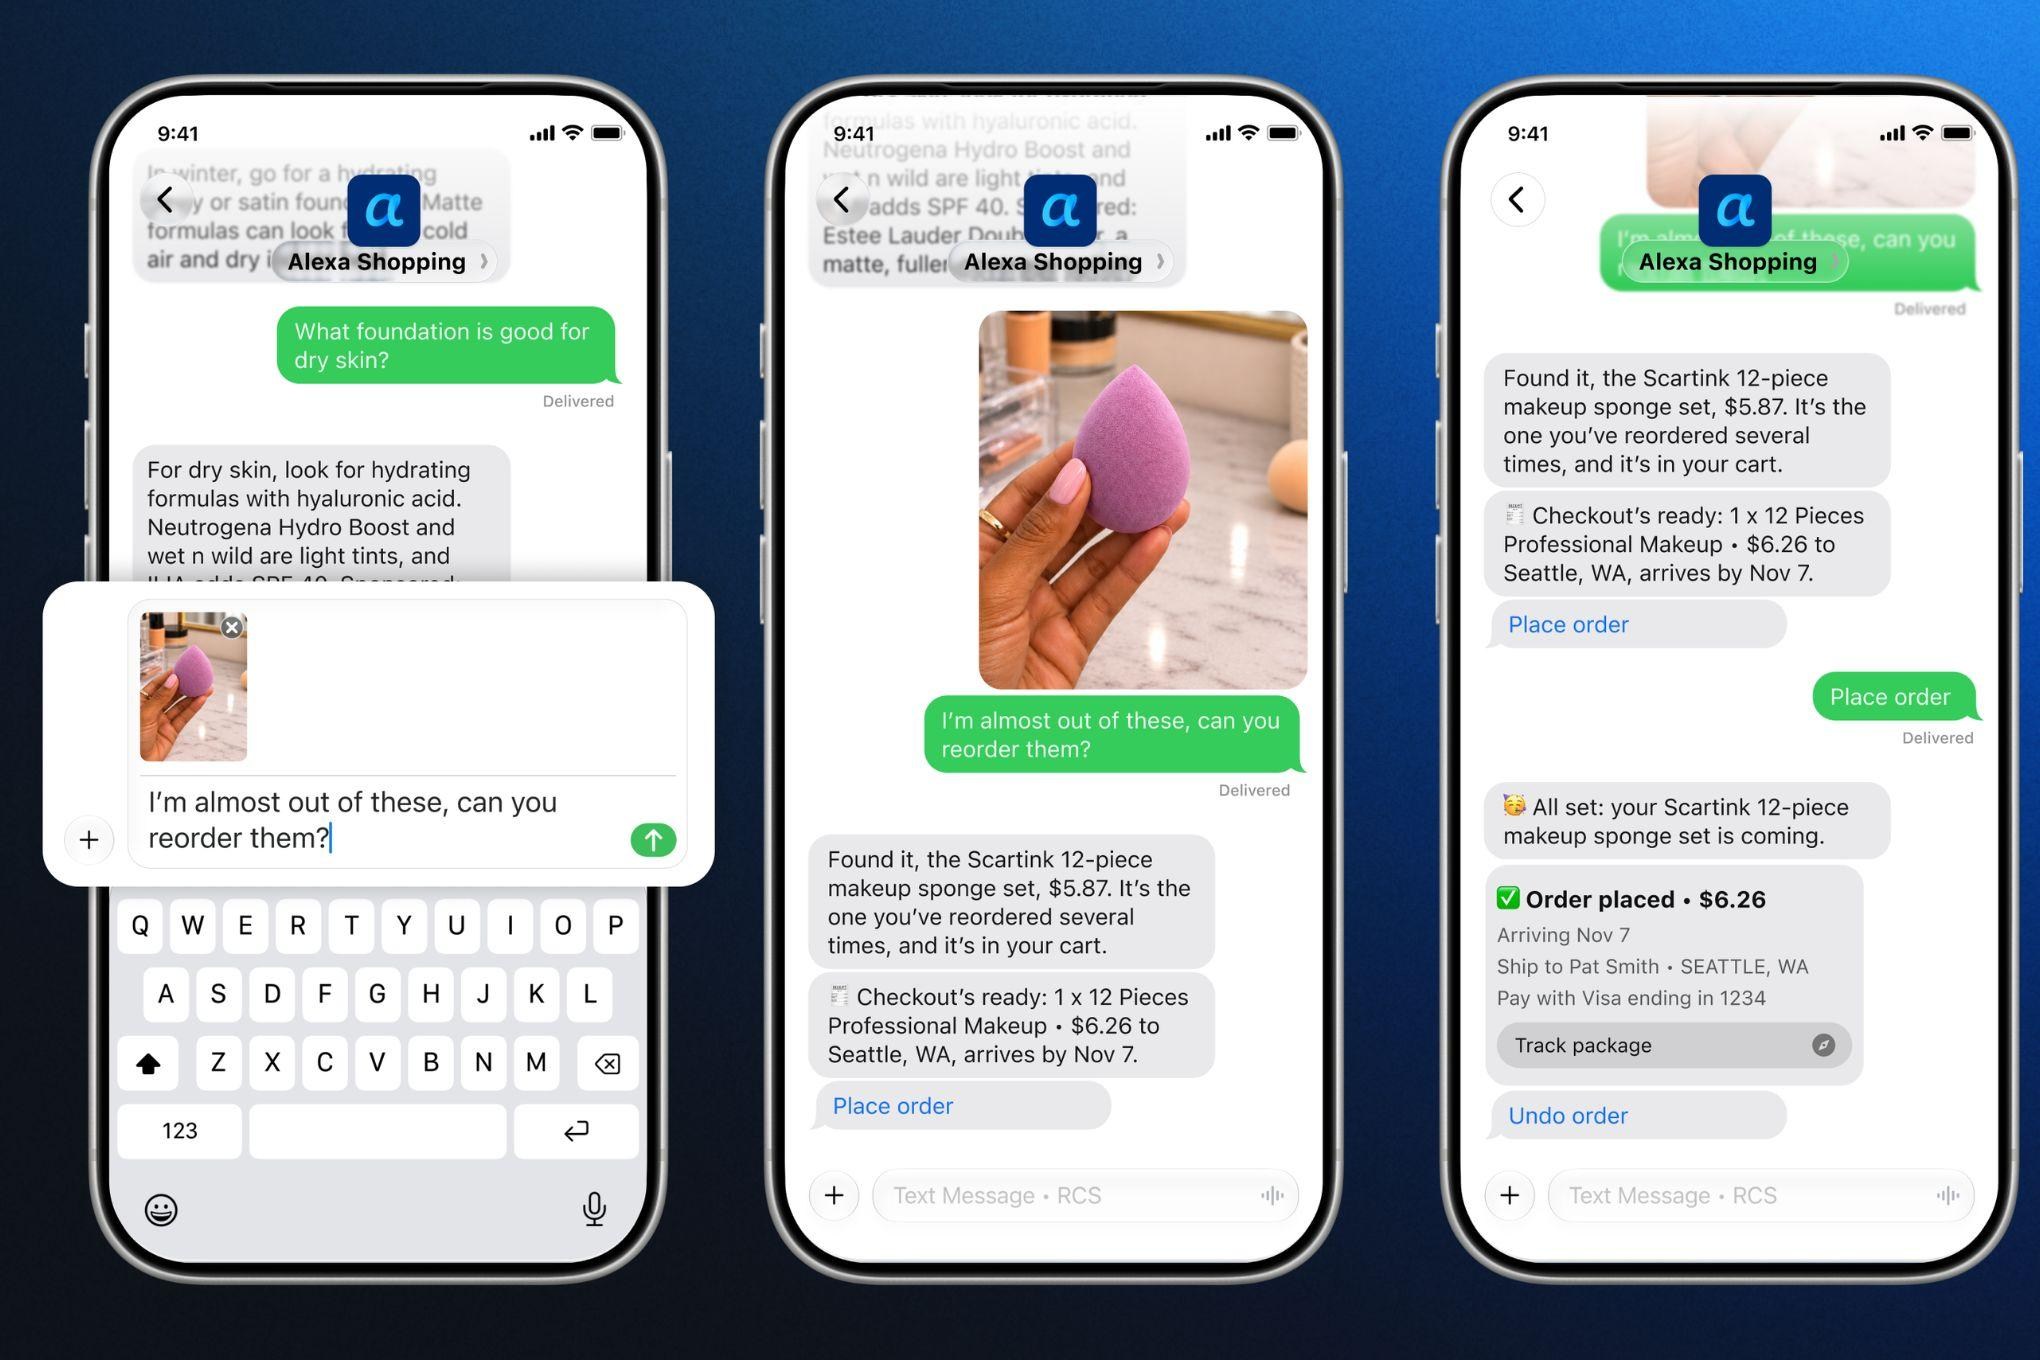 Amazon has added text search and ordering to Alexa for Shopping
November 6, 2026