mozgi
Dharma AI has introduced a tool for extracting data from documents
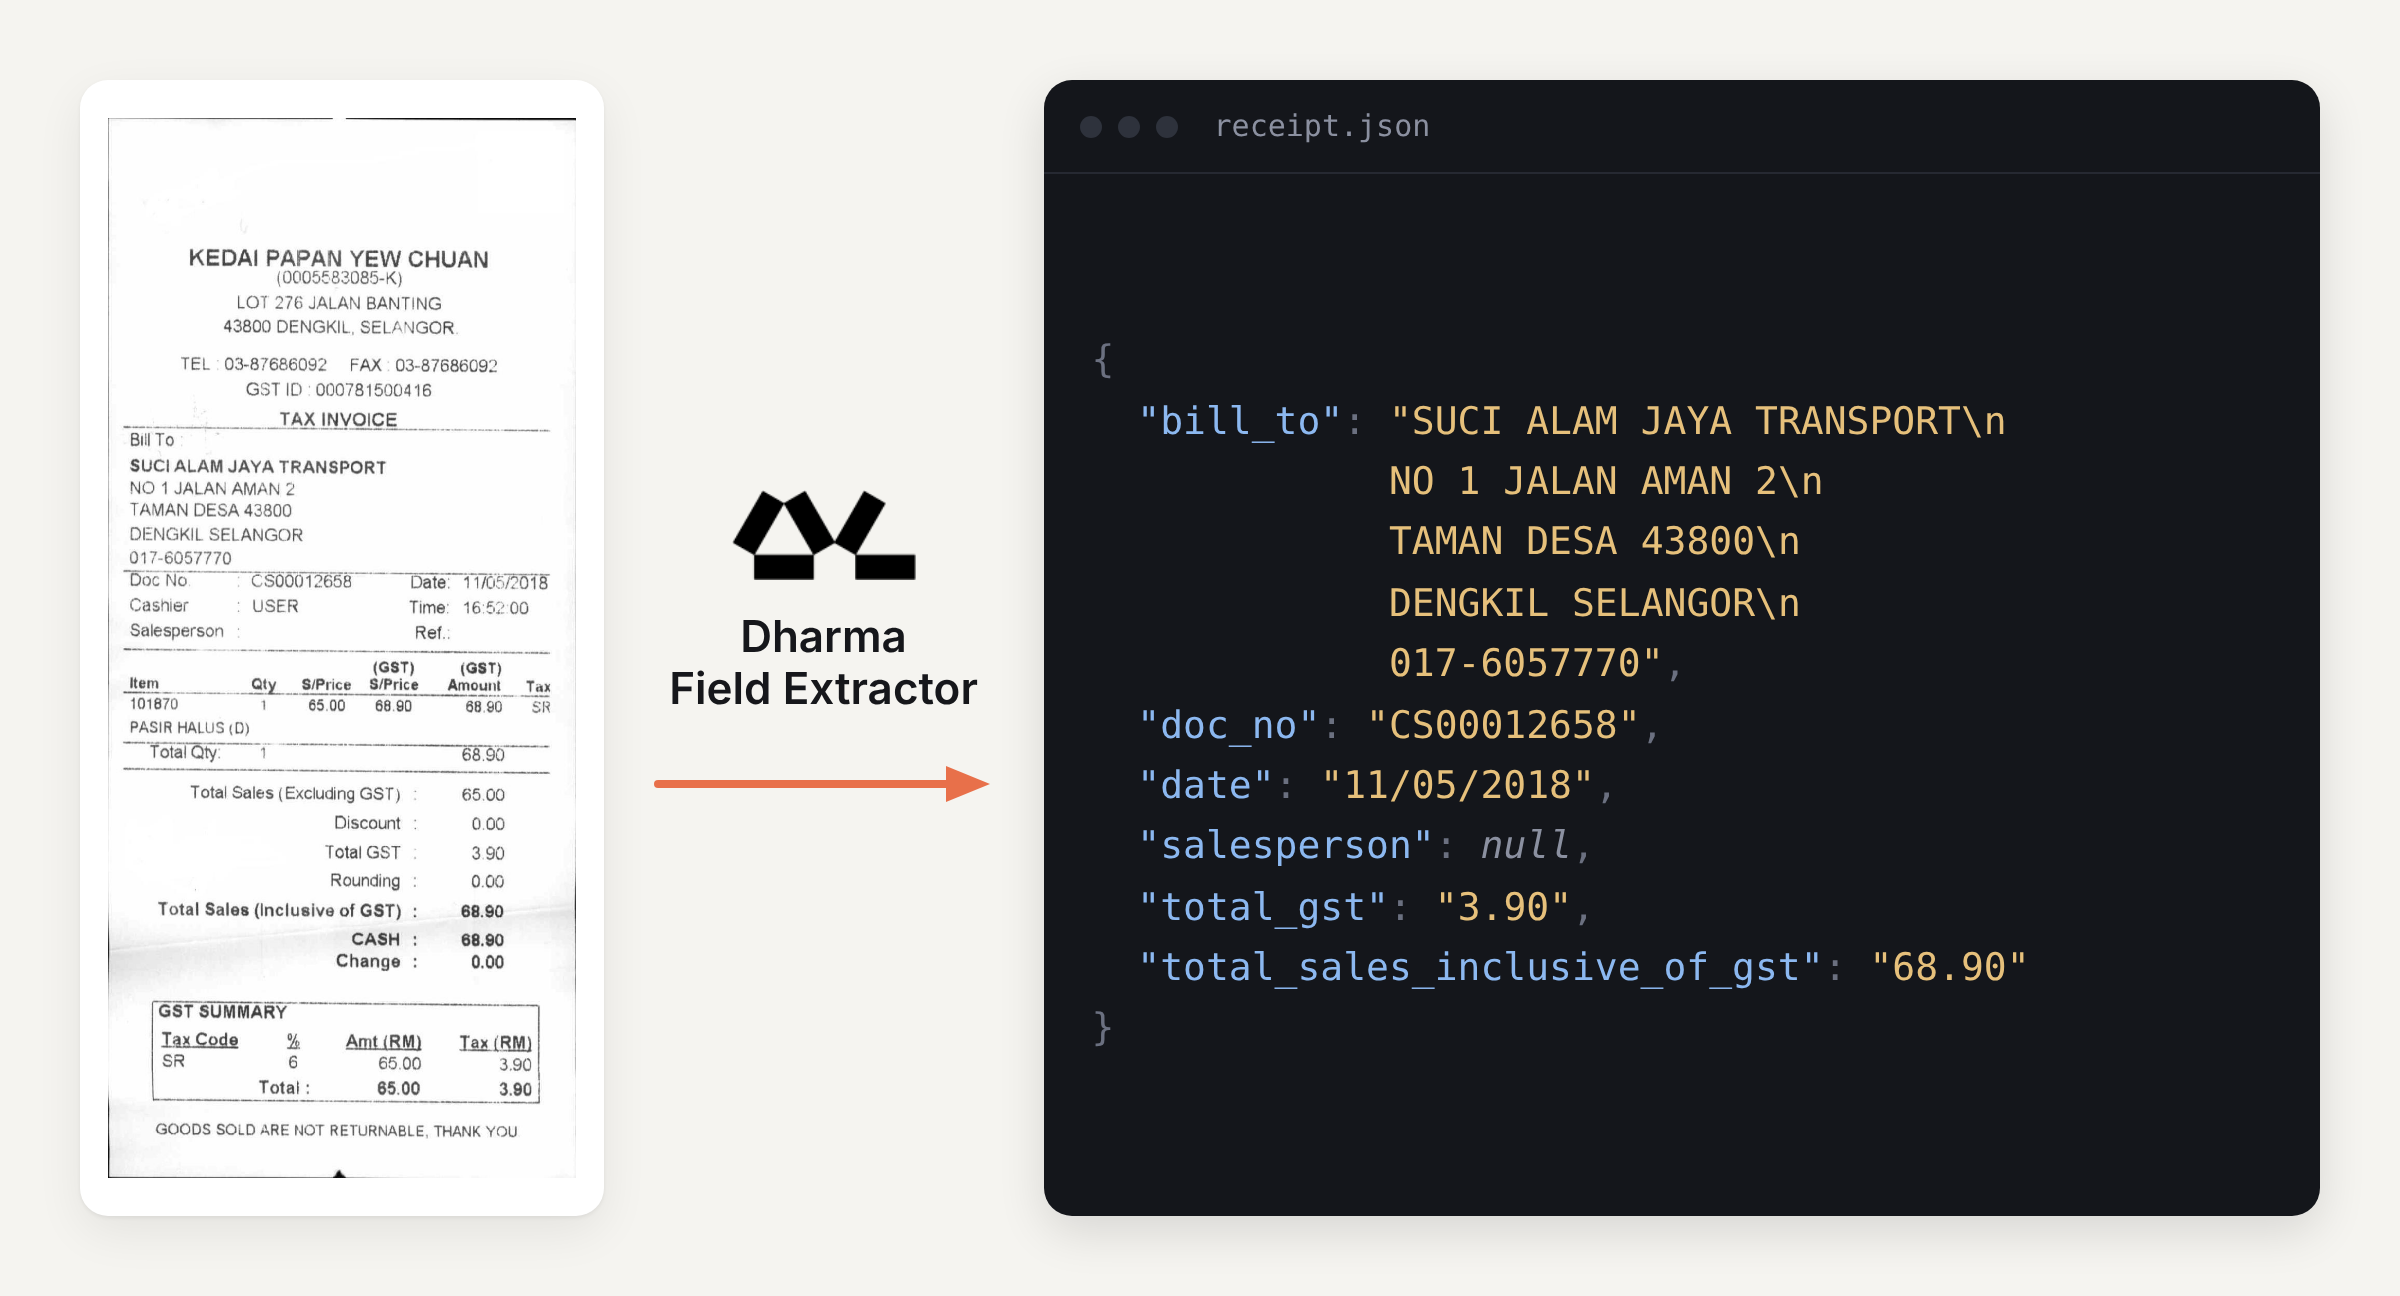
The Dharma AI team has released a specialized tool called Field Extractor, designed to automatically convert unstructured documents into JSON format. The system is developed to process arbitrary files, including PDFs, images, and text reports, by extracting data based on user-defined fields.
The core approach minimizes the need for complex pipeline configuration. The user defines a data schema, and the model independently analyzes the document content and maps the found information to the required keys. The tool supports multi-page files and complex table structures, ensuring high accuracy when extracting specific attributes such as invoice numbers, dates, or transaction amounts.
The developers emphasize the system's flexibility: it can adapt to various document formats without prior training on specific datasets. This allows the solution to be integrated into business processes that require rapid digitization of paper workflows or automated data entry from external sources.
For practitioners, this means the ability to reduce the time spent on manual processing of incoming documentation. The tool enables the automation of data extraction from heterogeneous sources, which is critical for accounting systems, financial analysis, and back-office automation, where the accuracy of field extraction directly impacts the quality of subsequent information processing.